

☆ Yσɠƚԋσʂ ☆
- 147 Posts
- 153 Comments



 2·5 days ago
You’re right, the patents do work that way unfortunately, and the premise is absolutely insane. The fact that you can come up with an idea all by yourself and not be allowed to use it because somebody else came up with it is just bonkers.

Exactly, the real issue is that they claim that people aren’t allowed to make clean room implementations of software that works with their hardware.
 8·7 days ago
I can only imagine how crazy that would’ve been.

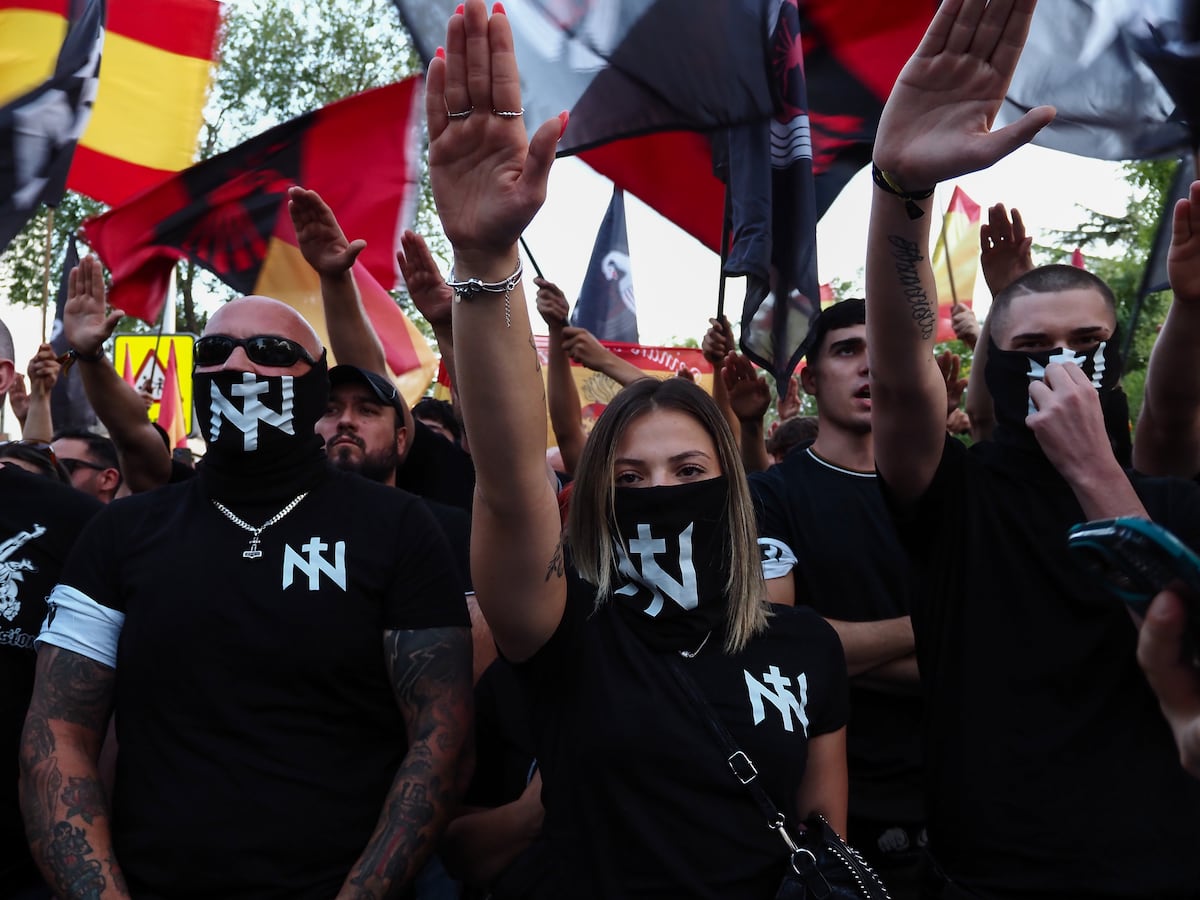


Decades of propaganda convinced people that Russia was a gas station with nukes, and it was easy to sell the narrative that the west just had to blow hard enough for Russian house of cards to fall apart. Initially, there was also a lot of buffer available, so the public didn’t really feel the effects of the war for the first couple of years. So, the war was being treated as an abstract thing that people didn’t connect with their day to day lives, and that coupled with the deep hatred of Russia in Europe made it easy to drum up support for draining Europe to fund the war. Now, the buffer has been run dry, and people are starting to realize there is a material cost to this whole adventure, but it might be too late to do anything about it. The damage has already been done, and Europe is going to be hobbled for decades to come even if the current regimes are overthrown.
good of people to start discovering why GPL exists
That’s right, Europeans are about to get Latin American treatment.
In fact, knee capping Europe appears to be an explicit goal here. The problem from American perspective is that Europe has natural economic interests aligned with China and Russia. The US can’t really offer anything of its own to counter that. So, if things were allowed to develop peacefully, the economic gravity would continue to shift to the east, and a political realignment would eventually follow. That would be a strategic disaster from American perspective, so it’s better to just burn Europe down instead.



 83·12 days ago
Any project is a sum of its parts, and if you’re talking about maintainability, then the parts you could easily point to would be things like high coupling, overly large file sizes, functions that are too big and should be broken up.
Meanwhile, your own link shows that it’s roughly within the ballpark of industry average. And if you look through issues for any large project on github you’ll see similar types of issues. Given how new the project is, none of this is really surprising or out of the ordinary.
As a note, nowhere did I suggest they do manual code reviews of everything at this speed. What I do think they have is a regression test suite which they build out as issues come up and they fix them.
I keep hearing people talk about trust, and it’s really doesn’t make sense to me because we’ve never done software development based on trust. Humans make mistakes all the time, and I’ve seen plenty far worse human code than anything an LLM has crapped out over my career. The way we ensure quality is through having a process. It’s done by having good specifications, testing, code reviews, planning, and so on. All these things equally apply to code written by hand and that’s generated by an LLM, and trust has nothing to do with it.
Can you point to which part specifically are you referring to here? https://github.com/storytold/photocraft
That’s only true for the US though. Electricity costs in China are a third of what they are in the states, and open models are now becoming very competitive. We can also see here that DeepSeek is already close to breaking even. The other factor is that models continue to get more efficient, and even local models like Qwen 27b can do serious work. Especially, when combined with good tooling. A coding harness that uses Qwen with five different roles scores as well as Anthropic Fable on the benchmarks.
I’ve been using them happily, and they do what I need. So, to me, this is real useful software that’s replacing proprietary solutions.

Large corps always end up implementing shitty practices because business practices are driven by pencil pushers. Even before LLMs, some of the most soul crushing jobs were found at large corps working with shit like J2EE. That’s nothing new really.
At my job, we use LLMs, but nobody is making 2k loc PRs all of a sudden, and we still pair up to review code, and generally work at human speed.
The only studies I’m aware of used tiny samples and produced muddled conclusions. If you have some conclusive empirical research then do feel free to share it though. Meanwhile, using LLMs doesn’t mean doing less, it just means focusing on different things. The skill deficit here is the same kind as the skill deficit people have using punch cards or writing assembly by hand today. As things become automated, different things become relevant and that’s what people shift their attention to.
https://en.wikipedia.org/wiki/Flag_of_the_Ukrainian_Insurgent_Army